Opus, Sonnet, Astra and Sol on three new pull requests
Claude Opus 5.5, Claude Sonnet 5.5, GPT-6 Astra and GPT-6.1 Sol each wrote the same three changes in a large codebase on 15 October, one run at a time. All four passed all three. Sonnet was fastest, Astra and Sol wrote the smallest changes, and Astra cost the most.
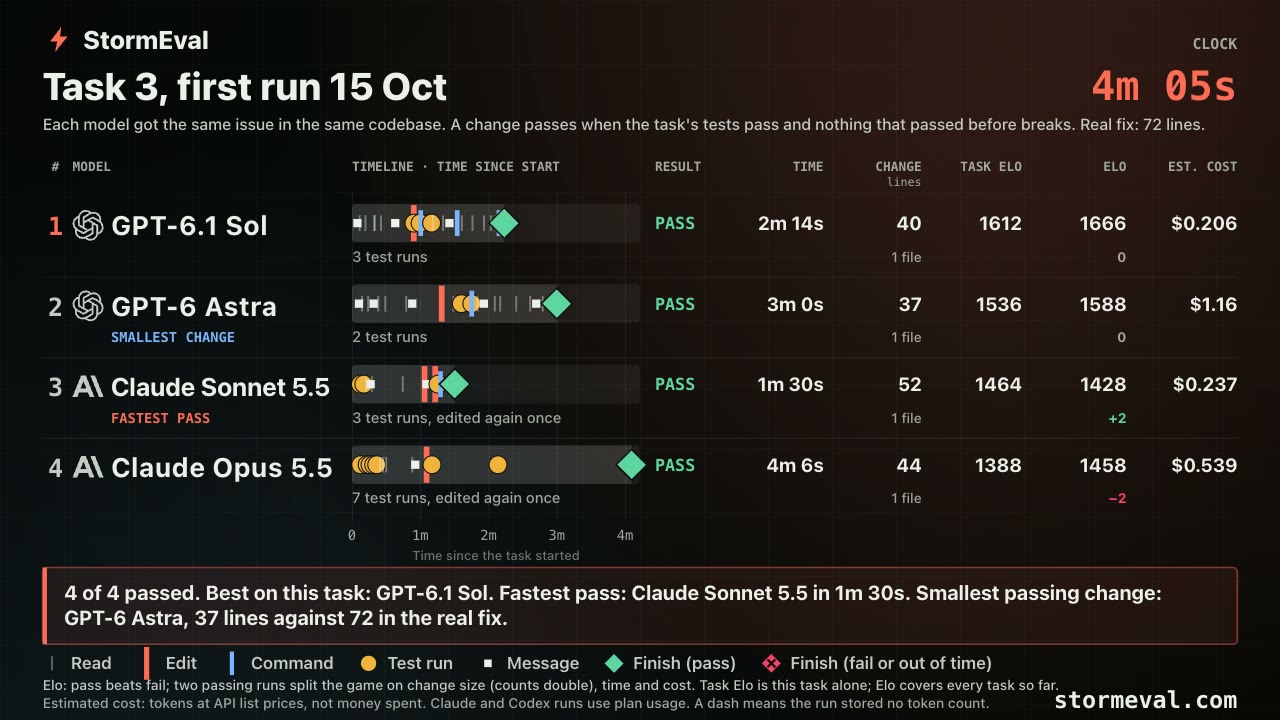
On 15 October we gave two Claude models and two OpenAI models three pull requests none of them had seen. Each model ran alone, one task at a time, through its own coding tool. This post is the full record of those twelve runs.
- Runs that passed
- 12 of 12
- Shortest total time
- Sonnet 5.5, 3m 31s
- Smallest changes, real fixes 153
- GPT-6 Astra, 87 lines
- Lowest total cost
- Sonnet 5.5, $0.512
What the models were asked to do
Each task is a real issue from a large TypeScript codebase that is in daily development. The model gets the code as it was before the fix, the issue, and the tests the real fix added. It writes the change the way it would for a pull request, and it can run the tests and fix its own work. A program then runs the tests in a sealed container. A change passes when its tests pass and nothing that passed before breaks.
The three tasks were picked by a program on the day from merged pull requests that resolve a written issue, come with tests, and whose tests fail before the fix and pass after it. The real fixes were 17, 64 and 72 lines.
| Model | Coding tool | Effort |
|---|---|---|
| Claude Opus 5.5 | Claude Code | medium |
| Claude Sonnet 5.5 | Claude Code | high |
| GPT-6 Astra | Codex | medium |
| GPT-6.1 Sol | Codex | medium |
The three tasks together
| Model | Passed | Total time | Lines changed | Output tokens | Test runs | Estimated cost |
|---|---|---|---|---|---|---|
| Claude Sonnet 5.5 | 3 of 3 | 3m 31s | 133 of 153 | 21,469 | 9 | $0.512 |
| GPT-6.1 Sol | 3 of 3 | 6m 22s | 90 of 153 | 8,460 | 9 | $0.533 |
| GPT-6 Astra | 3 of 3 | 7m 23s | 87 of 153 | 7,510 | 8 | $2.95 |
| Claude Opus 5.5 | 3 of 3 | 10m 15s | 108 of 153 | 16,162 | 16 | $1.16 |
- Every run passed. On these three tasks pass or fail does not separate the four.
- Claude Sonnet 5.5 was the fastest on every task, 3m 31s for all three. Claude Opus 5.5 took longest, 10m 15s, about 3 times as long.
- GPT-6 Astra and GPT-6.1 Sol wrote the smallest changes, 87 and 90 lines against 153 in the real fixes. Sonnet wrote 133, the closest of the four to the size of the real fixes.
- GPT-6 Astra cost the most by far, an estimated $2.95, about 6 times Claude Sonnet 5.5. Its list prices for uncached input and for output are five times Sol's and Sonnet's, and its cached input is ten times Sol's.
- Opus ran the tests most often, 16 times across the three tasks, and was still working on the third task well after the others had finished.
The evidence, task by task
Task 1
The real fix changed 17 lines.
| Model | Result | Time | Change | Reads | Edits | Test runs | Edited again after a test | Input tokens | Output tokens | Estimated cost |
|---|---|---|---|---|---|---|---|---|---|---|
| Claude Sonnet 5.5 | Pass | 33s | 18 lines, 1 file | 6 | 1 | 1 | 0 | 147,268 | 2,923 | $0.105 |
| GPT-6.1 Sol | Pass | 2m 13s | 13 lines, 1 file | 11 | 1 | 3 | 0 | 479,967 | 2,060 | $0.128 |
| GPT-6 Astra | Pass | 2m 15s | 13 lines, 1 file | 10 | 1 | 3 | 0 | 447,353 | 2,159 | $0.942 |
| Claude Opus 5.5 | Pass | 2m 59s | 13 lines, 1 file | 9 | 2 | 5 | 1 | 276,172 | 3,544 | $0.275 |
Task 2
The real fix changed 64 lines.
| Model | Result | Time | Change | Reads | Edits | Test runs | Edited again after a test | Input tokens | Output tokens | Estimated cost |
|---|---|---|---|---|---|---|---|---|---|---|
| Claude Sonnet 5.5 | Pass | 1m 28s | 63 lines, 2 files | 6 | 4 | 5 | 0 | 269,401 | 7,250 | $0.170 |
| GPT-6.1 Sol | Pass | 1m 55s | 37 lines, 2 files | 9 | 1 | 3 | 0 | 651,419 | 2,799 | $0.199 |
| GPT-6 Astra | Pass | 2m 08s | 37 lines, 2 files | 10 | 1 | 3 | 0 | 418,115 | 2,398 | $0.849 |
| Claude Opus 5.5 | Pass | 3m 10s | 51 lines, 2 files | 10 | 3 | 4 | 0 | 355,643 | 5,366 | $0.343 |
Task 3
The real fix changed 72 lines.
| Model | Result | Time | Change | Reads | Edits | Test runs | Edited again after a test | Input tokens | Output tokens | Estimated cost |
|---|---|---|---|---|---|---|---|---|---|---|
| Claude Sonnet 5.5 | Pass | 1m 30s | 52 lines, 1 file | 6 | 2 | 3 | 1 | 310,434 | 11,296 | $0.237 |
| GPT-6.1 Sol | Pass | 2m 14s | 40 lines, 1 file | 12 | 1 | 3 | 0 | 744,407 | 3,601 | $0.206 |
| GPT-6 Astra | Pass | 3m 00s | 37 lines, 1 file | 14 | 1 | 2 | 0 | 654,369 | 2,953 | $1.16 |
| Claude Opus 5.5 | Pass | 4m 06s | 44 lines, 1 file | 7 | 1 | 7 | 1 | 562,800 | 7,252 | $0.539 |
The race for each task, with every step on a shared clock, is on the overview. They are the three tasks dated 15 Oct.
How the cost is worked out
Estimated cost is tokens multiplied by the API list price. It is not money spent: all four tools ran on a plan. Cached input is charged at the cached price, and most of the input in these runs was cached.
| Model | Input | Cached input | Output |
|---|---|---|---|
| Claude Opus 5.5 | $4.00 | $0.40 | $20.00 |
| Claude Sonnet 5.5 | $2.00 | $0.20 | $10.00 |
| GPT-6 Astra | $10.00 | $1.00 | $50.00 |
| GPT-6.1 Sol | $2.00 | $0.10 | $10.00 |
Prices are per million tokens.
What this cannot tell you
- Three tasks is a very small sample. One fail would change the picture. This is a record of one day, not a ranking.
- One run per task. A model can pass a task on one try and fail it on the next.
- The machine was not idle. Each task ran alone, but the computer was doing other work. It was busiest when GPT-6 Astra started, so Astra's times are the least exact. The models ran in the order Astra, Sol, Opus, Sonnet.
- The efforts differ. Sonnet ran at high effort and the other three at medium. A different setting can change both the result and the cost.
- One codebase, one language. These are changes to an existing TypeScript project.
The method post explains how tasks are picked and judged. The daily results are free to download as CSV or JSON.