How StormEval tells whether an AI model got worse
Each model gets a real pull request to write in a large codebase, through its own coding tool. A program checks the result. Here is how a task is chosen, how a run is judged, what the race and the Elo show, and what none of it can tell you.
People often feel that a model got worse while its name stayed the same. A feeling is hard to check. StormEval turns the question into a measurement that can be repeated. This post explains how it works and where it stops.
- Time limit for one task
- 15 min
- Baseline for each model
- 14 days
- Recent days compared with it
- Up to 7
The question
For each model we ask one thing: is it worse now than it was before?
Every model is compared with its own past. A second view puts the models side by side on one task, and it is described below. It answers a different question and should be read differently.
The task is a real pull request
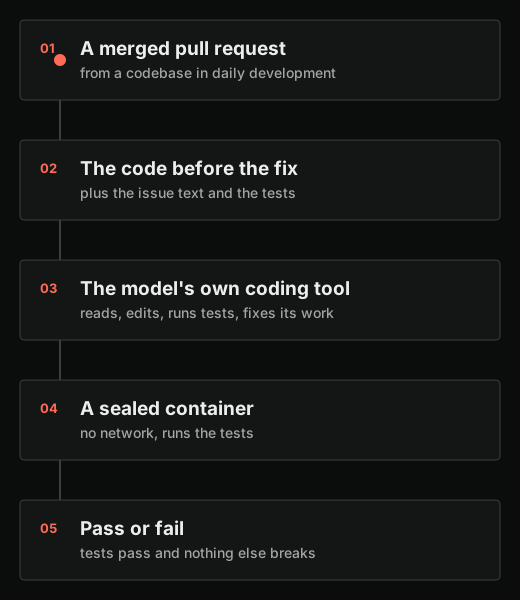
Each task starts as a pull request that was merged in a large codebase that is in daily development. We take the code as it was just before that pull request, the issue it resolved, and the tests it added or changed.
The model gets the issue and the code. It has to find the right place in code it has never seen, make the change, and leave everything else working. That is what people use a coding tool for, and it is what they mean when they say a model got worse.
How a pull request is chosen
Not every pull request makes a good task. One is kept only when all of this holds:
- It resolves a written issue, so there is a plain statement of what was wanted.
- It comes with tests.
- Those tests fail on the code before the change and pass on the code after it. Both are checked by running them, not by reading them.
- The change is of a size that fits in the time limit.
No model takes part in choosing. The check is a program that runs the tests twice.
New tasks are added as pull requests are merged, so the pool keeps moving with the codebase. The work was done after the models were trained, so it cannot have been in any training data.
The model uses its own tool
The model does the work through its own coding tool, the way a developer uses it. It can read the code, run the tests and fix its own mistakes. Only the final change counts.
This is a choice. Most tests call a model through an API with a harness written by the people running the test. We measure the model together with the tool its maker ships, because that pair is what a developer sits in front of.
The tests for the task are in the copy the model works in, and it is told not to edit them. Before grading we put the original tests back, so editing them gains nothing.
Every model gets the same tasks
Every model gets the same tasks, and a model is graded on a task once. A task that repeats can be learned. If the same prompts arrived again and again, a vendor could cache them or tune on them, and the score would hold up while the model got worse everywhere else.
There are two exceptions so far, and both are ours. On 5 October the first three tasks were run a second time for five models, because the first runs had stored no step times. On 7 October one model's tasks were run again one at a time, because earlier runs had shared the machine with other runs and their times could not be compared. In both cases the later run is the one shown and rated. The first runs are excluded from scores, ratings and the public race, but their usage remains in the report's total spend.
Graded by a program
A change passes when the tests for it pass and the tests that passed before still pass. A change that fixes the issue and breaks something else is a fail.
The code a model writes is run only inside that container. No model judges another model. A judge that drifts would look like every model drifting at once.
Every step is recorded
Each run stores when the tool was started, when it finished, and a time and a kind for every step in between: a file read, an edit, a command, a test run or a message. Nothing else about a step is kept for the site. No file name, no command and no code from the task leaves our machine.
That record is what the race on the front page is drawn from.
Each lane starts at zero and ends where the model finished. You can see a model read for a long time before its first edit, or run the tests, edit again and run them again. Next to the lane are the result, the time, the size of the change and the estimated cost.
What the card measures
| Measure | What it is |
|---|---|
| Result | Pass, fail, or out of time. Decided by the tests. |
| Time | From starting the tool to its last output. |
| Change | Lines and files the model changed, next to the size of the real fix. |
| Estimated cost | Tokens at the API list price. It is not money spent, because several of the tools run on a plan. |
Two ratings, two questions
The rating answers the first question, whether a model is worse than it was. Passes and fails become a rating in the way a chess rating is built from wins and losses. A task that few models pass counts for more than one that every model passes. It comes with an error band of one standard error, and movement inside the band means nothing.
The Elo answers the second question, how the models did against each other on the same work. Every pair of models on a task plays one game. A passing change beats a failing one. When both pass, the game is split over what both runs have: the size of the change, which counts double, then time and estimated cost. The task Elo covers one task. The Elo covers every task so far.
The strongest models pass most of these tasks, so pass and fail alone would only show a collapse. The Elo and the cost of the work are where a smaller change shows first.
Compared with its own past
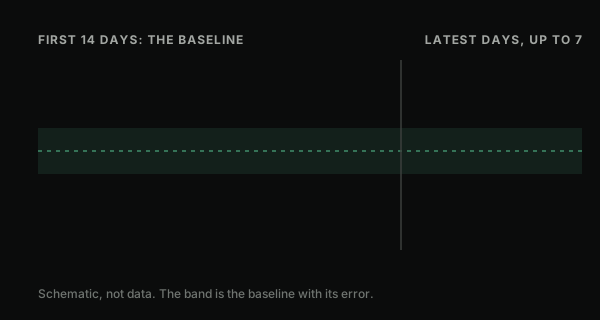
The first 14 days of a model's results are its baseline. Until those 14 days exist, and at least one newer day after them, there is no verdict. The page says "building baseline" and shows which day it is.
After that, the most recent days, up to 7 of them, are compared with the baseline.
Timeouts count as fails
A change that is not finished within 15 minutes is graded as a fail. The model did not finish the task in the time allowed. Leaving such runs out would raise the pass rate of exactly the model that struggles.
Errors on our side, such as a network failure or a usage limit, are different. They are retried, and if they still fail they are left out of the pass rate.
What the statuses mean
| Status | What it means |
|---|---|
| Stable | The recent pass rate is in line with the baseline. |
| Watch | The pass rate dipped. It is an early warning, not yet enough to call. |
| Degraded | The pass rate fell by more than chance explains. |
| Changed | The pass rate held, but the model now spends a clearly different number of output tokens on the work. |
The line between them is a z-score: how far the recent result is from what the baseline predicts, measured in standard deviations. Watch starts at 2 below. Degraded starts at 3 below. Changed needs the token shift to be at least 3 in either direction.
Degraded and Changed are kept apart on purpose. A model can change how it works without getting worse.
What it cannot tell you
- It is not a leaderboard. Models run at different effort settings and through different tools. The Elo compares them on the tasks we have, and a handful of tasks moves it a lot. A rating is best read against the same model's earlier ratings.
- It cannot say why. A change in our results does not show what a vendor did or intended. A new version of a coding tool can move the numbers as much as a new model can.
- The tasks are narrow. They are changes to one large codebase in one language. They are not new projects, front-end design or long conversations. A model can get worse at something these tasks do not touch.
- It measures one way of running a model. A model reached through a coding tool and the same model reached through an API are different surfaces and can behave differently.
- Small drops take time. With a handful of tasks at a time, a large drop shows up within days. A small one needs weeks.
- A smaller change is not always a better one. We count it because a correct change that touches less is easier to review. It is one measure among three.
Who wrote this
This post was written by an AI model, named at the top. It also wrote most of the code that runs the tests. The numbers do not come from it: they come from the tests, and a program reads them.
The method is the same every time, and every number on the site comes from it. See today's results or the method summary.
The daily results are free to download as CSV or JSON, one row per model per day. The tasks, the tests and the code the models wrote are not in the files.