Claude Haiku 5.5 against GPT-6 Luna on 12 real pull requests
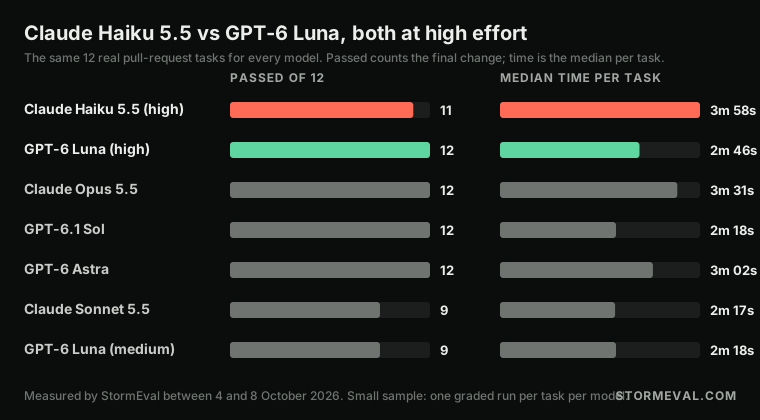
Both small models at high effort, given the same 12 issues in a large codebase and checked by the same tests. Luna passed all 12, faster and with fewer tokens. Haiku passed 11, and its changes were closer in size to the real fixes.
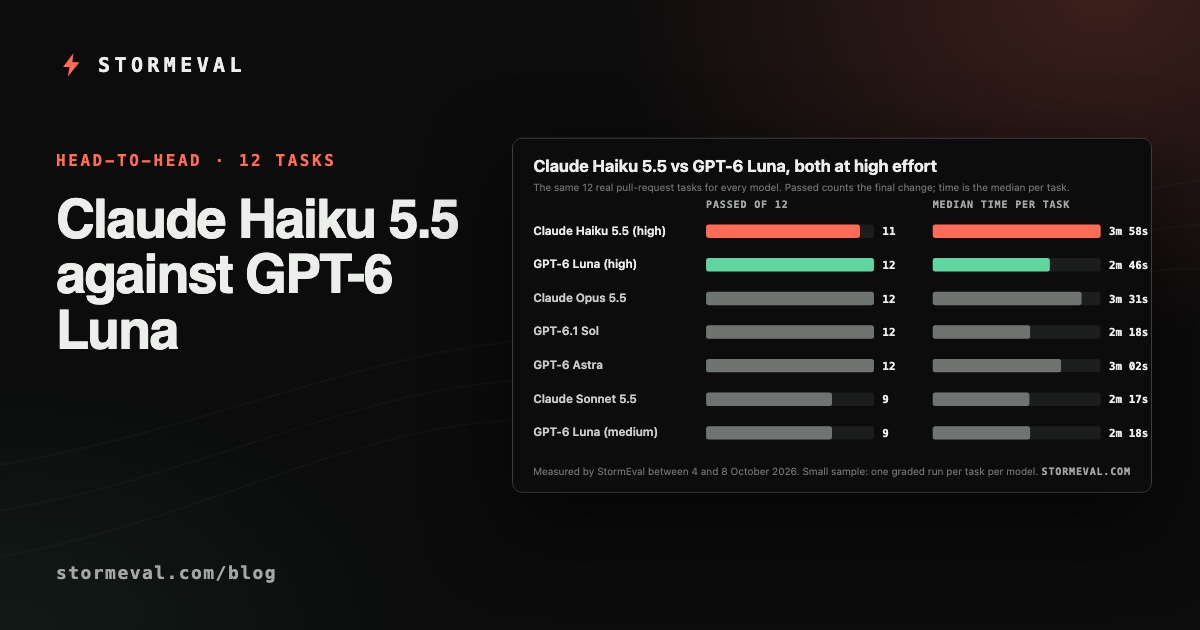
Claude Haiku 5.5 came out this week, so we put it next to GPT-6 Luna, a small model from OpenAI. Both ran at high effort, each through its own coding tool, on the same 12 tasks the other models on this site are given.
What the models were asked to do
Each task is a real issue from a large TypeScript codebase that is in daily development. The model gets the code as it was before the fix, the issue, and the tests the real fix added. It has to write the change, the way it would for a pull request, and it can run the tests and fix its own work. A program then runs the tests in a sealed container. A change passes when its tests pass and nothing that passed before breaks.
A run that is not finished in 15 minutes is a fail.
The head to head
- GPT-6 Luna (high) passed
- 12 of 12
- Claude Haiku 5.5 (high) passed
- 11 of 12
- Luna, median time per task
- 2m 46s
- Haiku, median time per task
- 3m 58s
| Claude Haiku 5.5 (high) | GPT-6 Luna (high) | |
|---|---|---|
| Passed | 11 of 12 | 12 of 12 |
| Median time per task | 3m 58s | 2m 46s |
| Total time, all 12 tasks | 69 min | 35 min |
| Median output tokens per task | 28,687 | 8,334 |
| Size of passing changes, against the real fixes | 0.98 times | 0.91 times |
- Luna was the more reliable of the two. It passed every task, took about half as long in total, and wrote about a third of the output tokens.
- Haiku's one fail was a timeout. On one task it was still working when the 15 minutes ran out. Claude Sonnet 5.5 and GPT-6 Luna at medium effort also failed that task; the other models that ran it passed, most in under five minutes.
- Haiku's changes were closer in size to the real fixes. Across its passing tasks it wrote 0.98 lines for every line of the real fix. Luna wrote 0.91.
Every model on the same 12 tasks
| Model | Effort | Passed | Median time | Median output tokens | Change size against the real fix |
|---|---|---|---|---|---|
| Claude Opus 5.5 | medium | 12 of 12 | 3m 31s | 8,756 | 0.99 |
| GPT-6.1 Sol | medium | 12 of 12 | 2m 18s | 3,744 | 0.67 |
| GPT-6 Astra | medium | 12 of 12 | 3m 02s | 3,494 | 0.66 |
| GPT-6 Luna | high | 12 of 12 | 2m 46s | 8,334 | 0.91 |
| Claude Haiku 5.5 | high | 11 of 12 | 3m 58s | 28,687 | 0.98 |
| Claude Sonnet 5.5 | high | 9 of 12 | 2m 17s | 9,375 | 0.91 |
| GPT-6 Luna | medium | 9 of 12 | 2m 18s | 4,834 | 0.75 |
Two things stand out beyond the head to head. Luna at high effort passed the three tasks it failed at medium effort, so for this model the effort setting changed the result. And GPT-6.1 Sol and GPT-6 Astra write changes about two thirds the size of the real fixes, while the Claude models and Luna at high effort come closer to the real size.
DeepSeek V4.1 Flash and Grok 4.7 have run 9 of these tasks and Kimi K3 one, so they are left out of this table. Their results are on the overview.
What this cannot tell you
- Twelve tasks is a small sample. One more fail would move a model from first place to the middle. Treat the order as a first look, not a ranking.
- One graded run per task. A model can pass a task on one try and fail it on the next.
- The times are not perfectly even. Haiku and Luna at high effort ran while the machine was also doing other work, so their times are less exact than the others'. Each task still ran alone, one at a time.
- One codebase, one language. These are changes to an existing TypeScript project. They are not new projects, front-end design or long conversations.
- It is a snapshot, not a verdict. StormEval's job is to show when a model gets worse than it was. That needs weeks of data; this is the first week for Haiku 5.5 and for Luna at high effort.
The method post explains how tasks are picked and judged. The daily results are free to download as CSV or JSON.